Pauli correlation encoding to reduce max-cut requirements
Usage estimate: 35 minutes on an Eagle r3 processor (NOTE: This is an estimate only. Your runtime might vary.)
Learning outcomes
- Understand the theoretical principles behind Pauli Correlation Encoding (PCE), including how multi‑body Pauli strings enable polynomial compression of classical optimization problems.
- Implement PCE in practice to encode and solve large‑scale optimization tasks on near‑term quantum hardware.
Prerequisites
Background
This tutorial presents Pauli Correlation Encoding (PCE) [1], an approach designed to encode optimization problems into qubits with greater efficiency for quantum computation. PCE maps classical variables in optimization problems to multi-body Pauli-matrix correlations, resulting in a polynomial compression of the problem's space requirements. By employing PCE, the number of qubits needed for encoding is reduced, making it particularly advantageous for near-term quantum devices with limited qubit resources. Furthermore, it is analytically demonstrated that PCE inherently mitigates barren plateaus, offering super-polynomial resilience against this phenomenon. This built-in feature enables unprecedented performance in quantum optimization solvers.
Overview
The PCE approach consists of three main steps, as illustrated in Figure 1 from [1] in below:
- Encoding the optimization problem into a Pauli correlation space.
- Solving the problem using a quantum-classical optimization solver.
- Decoding the solution back to the original optimization space. The PCE approach is adaptable to any quantum optimization solver capable of processing Pauli correlation matrices.

In Figure 1 from [1], the max-cut problem is used as an example to illustrate the PCE approach. The max-cut problem with nodes is encoded into a Pauli correlation space, representing the optimization problem as a correlation matrix — specifically, two-body Pauli-matrix correlations across qubits . Node colors indicate the Pauli string used for each encoded node. For example, node 1, which corresponds to binary variable , is encoded by the expectation value of , while is encoded by . This corresponds to compressing the problem's variables into qubits. More broadly, -body correlations enable polynomial compressions of order , with . The chosen Pauli set comprises three subsets of mutually-commuting Pauli strings, allowing all correlations to be experimentally estimated with only three measurement settings.
A loss function of Pauli expectation values that imitates the original max-cut objective function is constructed. The loss function is then optimized using a quantum-classical optimization solver, such as the Variational Quantum Eigensolver (VQE).
Once the optimization is complete, the solution is decoded back to the original optimization space, yielding the optimal max-cut solution.
Requirements
Before starting this tutorial, be sure you have the following installed:
- Qiskit SDK v1.0 or later, with visualization support
- Qiskit Runtime v0.22 or later (
pip install qiskit-ibm-runtime) - Optimization Mapper Qiskit addon (
pip install qiskit-addon-opt-mapper)
Setup
from itertools import combinations

import numpy as np
import rustworkx as rx
import networkx as nx

from scipy.optimize import minimize, OptimizeResult

from qiskit.circuit.library import efficient_su2
from qiskit.transpiler.preset_passmanagers import generate_preset_pass_manager
from qiskit.quantum_info import SparsePauliOp
from qiskit_ibm_runtime import EstimatorV2 as Estimator
from qiskit_ibm_runtime import QiskitRuntimeService
from qiskit_ibm_runtime import Session
from rustworkx.visualization import mpl_draw
from qiskit_aer import AerSimulator

from qiskit_addon_opt_mapper.applications import Maxcut
def make_cut_evaluator(problem):
"""Return a function that maps a 0/1 node assignment to its cut value.
The objective of the max-cut ``OptimizationProblem`` is the cut value
itself, and ``problem.objective.evaluate`` computes it for one
assignment. The swap search in Step 4 evaluates one candidate
assignment per edge, so pull the objective's coefficients out once
and evaluate them as a sparse matrix product instead.
"""
quadratic = problem.objective.quadratic.coefficients.tocsr()
linear = problem.objective.linear.to_array()
constant = problem.objective.constant
def evaluate_cut(bits):
x = np.asarray(bits, dtype=float)
return int(round(constant + linear @ x + x @ (quadratic @ x)))
return evaluate_cutSmall-scale simulator example
service = QiskitRuntimeService()
real_backend = service.least_busy(
    operational=True, simulator=False, min_num_qubits=156
)
backend = AerSimulator.from_backend(real_backend)
print(f"We are using the {backend.name}")
Output:
We are using the aer_simulator_from(ibm_pittsburgh)
Step 1: Map classical inputs to a quantum problem
The max-cut problem
The max-cut problem is a combinatorial optimization problem that is defined on a graph , where is the set of vertices and is the set of edges. The goal is to partition the vertices into two sets, and , such that the number of edges between the two sets is maximized. For the detailed description of the max-cut problem, please refer to the Quantum approximate optimization algorithm tutorial. The max-cut problem is also used as an example in the Advanced techniques for QAOA tutorial. In those tutorials, the QAOA algorithm is used to solve the max-cut problem.
Graph → optimization problem
Let us first consider a random graph with 100 nodes.
num_nodes = 100  # Number of nodes in graph
seed = 42
graph = rx.undirected_gnp_random_graph(num_nodes, 0.1, seed=seed)
mpl_draw(graph)
Output:
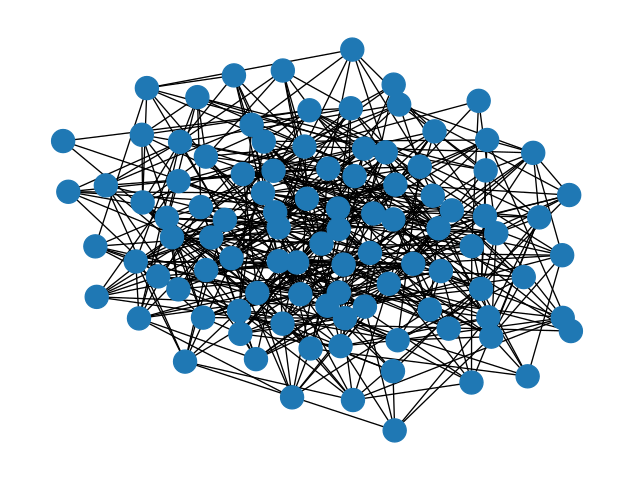
Model the max-cut problem with the Maxcut application class from the Optimization Mapper Qiskit addon. It returns an OptimizationProblem with one binary variable per node whose objective is the cut value to maximize. In the QAOA tutorials, this problem is converted to a QUBO and translated to a cost Hamiltonian with one qubit per variable. PCE instead encodes each binary variable into the sign of a Pauli expectation value, so here the problem defines and evaluates the objective, and the encoding into qubits follows below.
maxcut = Maxcut(graph)
maxcut_problem = maxcut.to_optimization_problem()
evaluate_cut = make_cut_evaluator(maxcut_problem)

print(f"Binary variables: {maxcut_problem.get_num_vars()}")
print(
    "Quadratic terms (one per edge):",
    len(maxcut_problem.objective.quadratic.to_dict()),
)
Output:
Binary variables: 100
Quadratic terms (one per edge): 508
nx_graph = nx.Graph()
nx_graph.add_nodes_from(range(num_nodes))
for edge in graph.edge_list():
nx_graph.add_edge(edge[0], edge[1])curr_cut_size, partition = nx.approximation.one_exchange(nx_graph, seed=1)
print(f"Initial cut size: {curr_cut_size}")Output:
Initial cut size: 345
We encode the graph with 100 nodes into two-body Pauli-matrix correlations across nine qubits (see the explanation below). The graph is represented as a correlation matrix, where each node is encoded by a Pauli string. The sign of the expectation value of the Pauli string indicates the partition of the node. For example, node 0 is encoded by a Pauli string, . The sign of the expectation value of this Pauli string indicates the partition of node 0. We define a Pauli-correlation encoding (PCE) relative to as
where is the partition of node and is the expectation value of the Pauli string encoding node over a quantum state .
Now, let's encode the graph into a Hamiltonian using PCE. We divide the nodes into three sets: , , and . Then, we encode the nodes in each set using the Pauli strings with , , and , respectively.
We need to extract a relationship between the number of nodes and qubits that we will need to encode all the nodes. Using all possible permutations for the encoding yields to:
In this example we consider , hence,
Therefore, the number of qubits needed to express a certain number of nodes read as:
Note that the symbol represents the ceiling function, which rounds any real number up to the next integer. This ensures that the number of qubits is an integer.
num_qubits = int(np.ceil((1 + np.sqrt(1 + (8 / 3) * num_nodes)) / 2))
list_size = num_nodes // 3
node_x = [i for i in range(list_size)]
node_y = [i for i in range(list_size, 2 * list_size)]
node_z = [i for i in range(2 * list_size, num_nodes)]
print(f"Number of qubits: {num_qubits}")
print("List 1:", node_x)
print("List 2:", node_y)
print("List 3:", node_z)Output:
Number of qubits: 9
List 1: [0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16, 17, 18, 19, 20, 21, 22, 23, 24, 25, 26, 27, 28, 29, 30, 31, 32]
List 2: [33, 34, 35, 36, 37, 38, 39, 40, 41, 42, 43, 44, 45, 46, 47, 48, 49, 50, 51, 52, 53, 54, 55, 56, 57, 58, 59, 60, 61, 62, 63, 64, 65]
List 3: [66, 67, 68, 69, 70, 71, 72, 73, 74, 75, 76, 77, 78, 79, 80, 81, 82, 83, 84, 85, 86, 87, 88, 89, 90, 91, 92, 93, 94, 95, 96, 97, 98, 99]
def build_pauli_correlation_encoding(pauli, node_list, n, k=2):
pauli_correlation_encoding = []
for idx, c in enumerate(combinations(range(n), k)):
if idx >= len(node_list):
break
paulis = ["I"] * n
paulis[c[0]], paulis[c[1]] = pauli, pauli
pauli_correlation_encoding.append(("".join(paulis)[::-1], 1))
hamiltonian = []
for pauli, weight in pauli_correlation_encoding:
hamiltonian.append(SparsePauliOp.from_list([(pauli, weight)]))
return hamiltonian
pauli_correlation_encoding_x = build_pauli_correlation_encoding(
"X", node_x, num_qubits
)
pauli_correlation_encoding_y = build_pauli_correlation_encoding(
"Y", node_y, num_qubits
)
pauli_correlation_encoding_z = build_pauli_correlation_encoding(
"Z", node_z, num_qubits
)Step 2: Optimize problem for quantum hardware execution
Quantum circuit
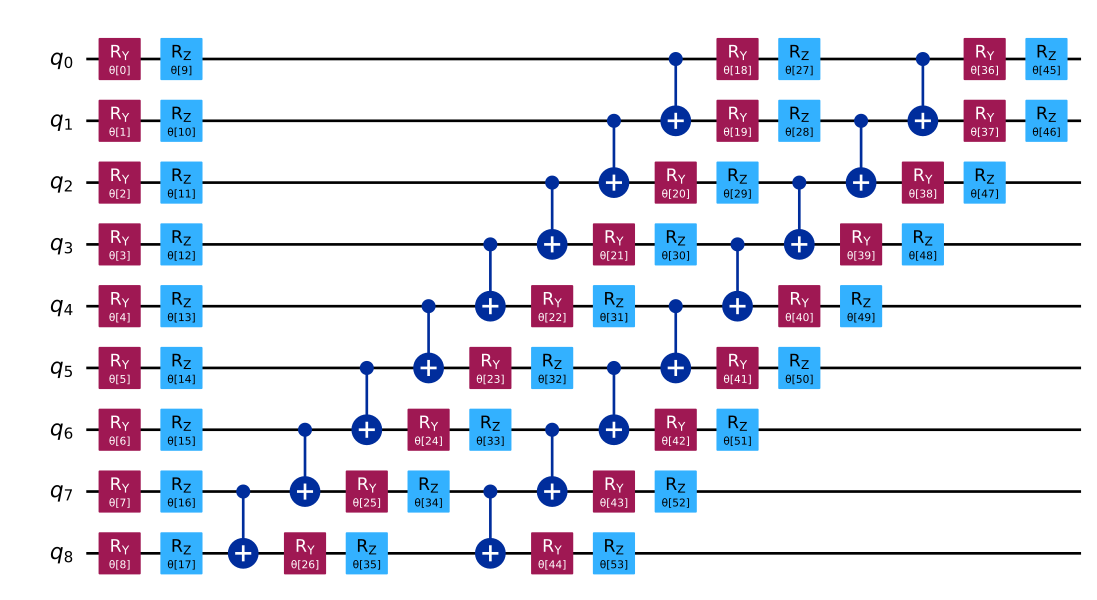
Here, the state is parameterized with , and we optimize these parameters using a variational approach.
This tutorial employs the efficient_su2 ansatz for our variational algorithm due to its expressive capabilities and ease of implementation.
We also use the relaxed loss function, which will be introduced later in this tutorial.
As a result, we can address large-scale problems with fewer qubits and shallower circuit depths.
# Build the quantum circuit
qc = efficient_su2(num_qubits, su2_gates=["ry", "rz"], reps=2)
qc.draw("mpl")Output:
# Optimize the circuit
pm = generate_preset_pass_manager(optimization_level=3, backend=backend)
qc = pm.run(qc)Loss function
For the loss function , we use a relaxation of the max-cut objective function as described in [1], which is defined as . Here, denotes the weight of the edge , and represents the partition of node . The loss function is given by:
,
where the max-cut objective function is replaced by the smooth hyperbolic tangents of the expectation values of the Pauli strings encoding the nodes. The regularization term and the rescaling factor , proportional to the number of qubits, are introduced to improve the solver's performance.
The regularization term is defined as:
is defined as
where , , is the number of edges, and is the number of nodes in the graph.
def loss_func_estimator(x, ansatz, hamiltonian, estimator, graph):
"""
Calculates the specified loss function for the given ansatz, Hamiltonian,
and graph.
The expectation values of each Pauli string in the Hamiltonian are first
obtained by running the ansatz on the quantum backend. These
expectation values are then passed through the nonlinear function
tanh(alpha * prod_i). The loss function is
subsequently computed from these transformed values.
"""
job = estimator.run(
[
(ansatz, hamiltonian[0], x),
(ansatz, hamiltonian[1], x),
(ansatz, hamiltonian[2], x),
]
)
result = job.result()
# calculate the loss function
node_exp_map = {}
idx = 0
for r in result:
for ev in r.data.evs:
node_exp_map[idx] = ev
idx += 1
loss = 0
alpha = num_qubits
for edge0, edge1 in graph.edge_list():
loss += np.tanh(alpha * node_exp_map[edge0]) * np.tanh(
alpha * node_exp_map[edge1]
)
regulation_term = 0
for i in range(len(graph.nodes())):
regulation_term += np.tanh(alpha * node_exp_map[i]) ** 2
regulation_term = regulation_term / len(graph.nodes())
regulation_term = regulation_term**2
beta = 1 / 2
v = len(graph.edges()) / 2 + (len(graph.nodes()) - 1) / 4
regulation_term = beta * v * regulation_term
loss = loss + regulation_term
global experiment_result
print(f"Iter {len(experiment_result)}: {loss}")
experiment_result.append({"loss": loss, "exp_map": node_exp_map})
return lossStep 3: Execute using Qiskit primitives
In this tutorial, we set max_iter=50 in the optimization loop for demonstration purposes. If we increase the number of iterations, we can expect better results.
pce = []
pce.append(
[op.apply_layout(qc.layout) for op in pauli_correlation_encoding_x]
)
pce.append(
[op.apply_layout(qc.layout) for op in pauli_correlation_encoding_y]
)
pce.append(
[op.apply_layout(qc.layout) for op in pauli_correlation_encoding_z]
)max_iter = 50
counter = {"i": 0}
last_x = {"value": None}
last_fun = {"value": None}
with Session(backend=backend) as session:
estimator = Estimator(mode=session)
experiment_result = []
def loss_func(x):
last_x["value"] = x.copy()
if counter["i"] + 1 > max_iter:
return last_fun["value"]
counter["i"] += 1
val = loss_func_estimator(
x, qc, [pce[0], pce[1], pce[2]], estimator, graph
)
last_fun["value"] = val
return val
np.random.seed(seed)
initial_params = np.random.rand(qc.num_parameters)
result = minimize(
loss_func, initial_params, method="COBYLA", options={"rhobeg": 1.0}
)
if counter["i"] >= max_iter:
result = OptimizeResult(
message=f"Return from COBYLA because the objective function "
f"has been evaluated {max_iter} times.",
success=False,
status=3,
fun=last_fun["value"],
x=last_x["value"],
nfev=counter["i"],
)
print(result)Output:
Iter 0: 152.06331779109445
Iter 1: 126.93132569244693
Iter 2: 55.00651109478942
Iter 3: 33.21667439735082
Iter 4: 19.167189700765054
Iter 5: 30.426875553389127
Iter 6: 13.906354614925815
Iter 7: 27.668686100172614
Iter 8: 28.194600411380772
Iter 9: 24.899677141564936
Iter 10: 22.10858041608358
Iter 11: 8.096210209030176
Iter 12: 8.761240650022913
Iter 13: 9.43332962472133
Iter 14: 7.559669820210062
Iter 15: 13.023860357384214
Iter 16: 11.953653163007987
Iter 17: 10.434221292269214
Iter 18: 4.871246922225549
Iter 19: 10.303826533395856
Iter 20: 16.40225843511339
Iter 21: 10.852469442638652
Iter 22: 9.314666066331633
Iter 23: 6.082358010011717
Iter 24: 10.982893700414476
Iter 25: 4.575556036893407
Iter 26: 6.844995727798197
Iter 27: 8.695229718011293
Iter 28: 3.730227705075576
Iter 29: 4.285479467758721
Iter 30: 4.219714169314187
Iter 31: 0.21125608131726548
Iter 32: 4.22820465672552
Iter 33: 13.67513152473414
Iter 34: 10.388838701884863
Iter 35: -0.5400153834163355
Iter 36: 5.310281742761159
Iter 37: -0.5430772019249082
Iter 38: -4.47820293096989
Iter 39: -3.4832056790567467
Iter 40: -0.5087341672330172
Iter 41: -2.488777859669888
Iter 42: 0.34945469121089356
Iter 43: -0.8544299675507805
Iter 44: -3.5902371208579344
Iter 45: 2.6609573847203216
Iter 46: -4.336467834641085
Iter 47: 0.10158504073828034
Iter 48: -1.3506458813942084
Iter 49: -2.1794894170194192
message: Return from COBYLA because the objective function has been evaluated 50 times.
success: False
status: 3
fun: -2.1794894170194192
x: [ 1.375e+00 1.951e+00 ... 9.395e-01 8.948e-01]
nfev: 50
Step 4: Post-process and return result in desired classical format
The partitions of the nodes are determined by evaluating the sign of the expectation values of the Pauli strings that encode the nodes. A non-negative expectation value assigns the node the value 1, and a negative expectation value assigns 0. The interpret method of Maxcut then decodes this assignment into the two node sets.
# Decode the node assignment from the iteration with the lowest loss.
# If the expectation value is non-negative, the node is assigned 1,
# otherwise it is assigned 0.
def get_bits(experiment_result):
best_index = min(
range(len(experiment_result)),
key=lambda i: experiment_result[i]["loss"],
)
exp_map = experiment_result[best_index]["exp_map"]
bits = [1 if exp_map[i] >= 0 else 0 for i in range(len(exp_map))]
return bits, best_index
cur_bits, best_index = get_bits(experiment_result)
partition = maxcut.interpret(np.array(cur_bits))
print("Partition 0:", partition[0])
print("Partition 1:", partition[1])Output:
Partition 0: [0, 1, 3, 5, 6, 7, 9, 11, 12, 14, 15, 17, 22, 24, 25, 28, 31, 32, 33, 35, 37, 38, 39, 40, 41, 43, 49, 53, 54, 56, 59, 61, 63, 65, 67, 68, 69, 77, 78, 79, 80, 88, 92, 93, 94, 95]
Partition 1: [2, 4, 8, 10, 13, 16, 18, 19, 20, 21, 23, 26, 27, 29, 30, 34, 36, 42, 44, 45, 46, 47, 48, 50, 51, 52, 55, 57, 58, 60, 62, 64, 66, 70, 71, 72, 73, 74, 75, 76, 81, 82, 83, 84, 85, 86, 87, 89, 90, 91, 96, 97, 98, 99]
We can calculate the cut size of the max-cut problem by evaluating the objective of the OptimizationProblem on this assignment.
cut_size = evaluate_cut(cur_bits)
print(f"Cut size: {cut_size}")Output:
Cut size: 278
Once the training is complete, we perform one round of single-bit swap search to improve the solution as a classical post-processing step. In this process, we swap the partitions of two nodes and evaluate the cut size. If the cut size is improved, we keep the swap. We repeat this process for all possible pairs of nodes connected by an edge.
# Swap the partitions and calculate the cut size
def swap_partitions(graph, cur_bits, evaluate_cut):
best_cut = 0
best_bits = []
for edge0, edge1 in graph.edge_list():
swapped_bits = cur_bits.copy()
swapped_bits[edge0], swapped_bits[edge1] = (
swapped_bits[edge1],
swapped_bits[edge0],
)
cut_size = evaluate_cut(swapped_bits)
if best_cut < cut_size:
best_cut = cut_size
best_bits = swapped_bits
return best_cut, best_bits
best_cut, best_bits = swap_partitions(graph, cur_bits, evaluate_cut)
print(best_cut, best_bits)Output:
287 [0, 0, 1, 0, 1, 0, 0, 0, 1, 0, 1, 0, 0, 1, 0, 0, 1, 0, 1, 1, 1, 1, 0, 1, 0, 0, 1, 1, 0, 1, 1, 0, 0, 0, 1, 1, 0, 0, 0, 0, 0, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 1, 1, 0, 0, 1, 0, 1, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 0, 0, 0, 0, 1, 1, 1, 1]
Large-scale hardware example
# -------------------------Step 1-------------------------
num_nodes = 1500 # Number of nodes in graph
graph = rx.undirected_gnp_random_graph(num_nodes, 0.1, seed=seed)
nx_graph = nx.Graph()
nx_graph.add_nodes_from(range(num_nodes))
for edge in graph.edge_list():
    nx_graph.add_edge(edge[0], edge[1])
maxcut = Maxcut(graph)
maxcut_problem = maxcut.to_optimization_problem()
evaluate_cut = make_cut_evaluator(maxcut_problem)
num_qubits = int(np.ceil((1 + np.sqrt(1 + (8 / 3) * num_nodes)) / 2))
list_size = num_nodes // 3
node_x = [i for i in range(list_size)]
node_y = [i for i in range(list_size, 2 * list_size)]
node_z = [i for i in range(2 * list_size, num_nodes)]
pauli_correlation_encoding_x = build_pauli_correlation_encoding(
"X", node_x, num_qubits
)
pauli_correlation_encoding_y = build_pauli_correlation_encoding(
"Y", node_y, num_qubits
)
pauli_correlation_encoding_z = build_pauli_correlation_encoding(
"Z", node_z, num_qubits
)
print(f"We are using {num_qubits} qubits")
# -------------------------Step 2-------------------------
backend = real_backend
print(f"We are using the {backend.name}")
qc = efficient_su2(num_qubits, ["ry", "rz"], reps=2)
pm = generate_preset_pass_manager(optimization_level=3, backend=backend)
qc = pm.run(qc)
# -------------------------Step 3-------------------------
pce = []
pce.append(
    [op.apply_layout(qc.layout) for op in pauli_correlation_encoding_x]
)
pce.append(
    [op.apply_layout(qc.layout) for op in pauli_correlation_encoding_y]
)
pce.append(
    [op.apply_layout(qc.layout) for op in pauli_correlation_encoding_z]
)
# Run the optimization using a session.
max_iter = 50
counter = {"i": 0}
with Session(backend=backend) as session:
estimator = Estimator(mode=session)
estimator.options.environment.job_tags = ["TUT_PCEFQ"]
experiment_result = []
def loss_func(x):
last_x["value"] = x.copy()
if counter["i"] + 1 > max_iter:
return last_fun["value"]
counter["i"] += 1
val = loss_func_estimator(
x, qc, [pce[0], pce[1], pce[2]], estimator, graph
)
last_fun["value"] = val
return val
np.random.seed(seed)
initial_params = np.random.rand(qc.num_parameters)
result = minimize(
loss_func, initial_params, method="COBYLA", options={"rhobeg": 1.0}
)
if counter["i"] >= max_iter:
result = OptimizeResult(
message=f"Return from COBYLA because the objective function "
f"has been evaluated {max_iter} times.",
success=False,
status=3,
fun=last_fun["value"],
x=last_x["value"],
nfev=counter["i"],
)
print(result)
# -------------------------Step 4-------------------------
cur_bits, best_index = get_bits(experiment_result)
cut_size = evaluate_cut(cur_bits)
print(f"Cut size: {cut_size}")
best_cut, best_bits = swap_partitions(graph, cur_bits, evaluate_cut)
# Print final solution
print(
f"The best max-cut value achieved for a graph with {num_nodes} nodes "
f"on {num_qubits} qubits is {best_cut}"
)
print(f"and the specific partition we obtained is {best_bits}")Output:
We are using 33 qubits
We are using the ibm_pittsburgh
Iter 0: 62192.56098951446
Iter 1: 54325.76340818571
Iter 2: 42933.215216568526
Iter 3: 35721.92960658595
Iter 4: 35947.69927402131
Iter 5: 38563.731543582166
Iter 6: 32552.97070835923
Iter 7: 34730.314616527576
Iter 8: 27032.920190652876
Iter 9: 27126.107795624957
Iter 10: 25268.853826648774
Iter 11: 23521.1489346676
Iter 12: 21658.585394613096
Iter 13: 15154.765728388778
Iter 14: 14826.985321939152
Iter 15: 16199.811009055386
Iter 16: 14328.589985020852
Iter 17: 13542.67789354434
Iter 18: 11737.341026421902
Iter 19: 10986.431644208033
Iter 20: 9780.61657788984
Iter 21: 8555.757154943312
Iter 22: 10465.489221259657
Iter 23: 8577.158776664453
Iter 24: 8950.176436175909
Iter 25: 7395.8803219317215
Iter 26: 7228.1129297581765
Iter 27: 6881.076354027118
Iter 28: 6626.8983738084835
Iter 29: 7302.433279572058
Iter 30: 6995.735525608492
Iter 31: 6176.828001182083
Iter 32: 6299.8061884979725
Iter 33: 6498.921256598082
Iter 34: 6184.684072713035
Iter 35: 5707.720358527108
Iter 36: 5414.328928670104
Iter 37: 5771.80573980932
Iter 38: 5620.64903695431
Iter 39: 6285.735849503706
Iter 40: 5894.367571492991
Iter 41: 6079.275064349491
Iter 42: 5267.448536682269
Iter 43: 4789.7281459863325
Iter 44: 5109.106057200384
Iter 45: 5060.248865782273
Iter 46: 5064.786713246322
Iter 47: 5474.433264995371
Iter 48: 4675.6138719238015
Iter 49: 5081.660754434205
 message: Return from COBYLA because the objective function has been evaluated 50 times.
 success: False
  status: 3
     fun: 5081.660754434205
       x: [ 1.375e+00  1.951e+00 ...  7.260e-01  8.971e-01]
    nfev: 50
Cut size: 55507
The best max-cut value achieved for a graph with 1500 nodes on 33 qubits is 55567
and the specific partition we obtained is [1, 0, 0, 1, 1, 1, 1, 0, 0, 1, 1, 1, 0, 1, 0, 1, 0, 0, 0, 1, 1, 0, 1, 0, 0, 1, 1, 0, 0, 1, 1, 1, 0, 0, 0, 0, 0, 1, 0, 0, 0, 1, 1, 1, 1, 0, 0, 0, 0, 1, 0, 0, 0, 0, 1, 1, 1, 0, 1, 1, 1, 0, 1, 0, 0, 0, 0, 0, 0, 1, 0, 1, 1, 0, 0, 1, 1, 1, 1, 0, 1, 0, 1, 1, 0, 1, 1, 0, 0, 0, 1, 1, 1, 0, 1, 1, 0, 0, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 0, 0, 0, 1, 1, 0, 1, 0, 1, 0, 1, 0, 1, 1, 1, 0, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0, 0, 1, 0, 1, 1, 1, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 0, 0, 0, 0, 1, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 0, 0, 0, 0, 0, 0, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 1, 1, 0, 0, 0, 0, 0, 1, 0, 0, 0, 0, 0, 1, 0, 1, 0, 0, 0, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 1, 0, 0, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 0, 1, 1, 0, 1, 1, 1, 0, 0, 0, 0, 1, 1, 1, 1, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 0, 0, 0, 1, 0, 0, 0, 1, 1, 1, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 1, 1, 0, 0, 0, 1, 0, 1, 0, 0, 1, 0, 1, 1, 1, 0, 0, 1, 1, 1, 1, 1, 0, 1, 0, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 1, 1, 0, 1, 1, 1, 1, 0, 0, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 0, 1, 0, 1, 0, 0, 0, 0, 0, 1, 0, 0, 1, 0, 0, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 1, 1, 1, 0, 0, 0, 1, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 0, 0, 1, 0, 0, 0, 1, 0, 0, 1, 1, 1, 0, 0, 0, 0, 1, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 0, 1, 1, 0, 1, 1, 1, 1, 0, 1, 0, 1, 0, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 1, 1, 1, 0, 0, 1, 1, 1, 0, 0, 1, 0, 1, 1, 0, 1, 1, 1, 1, 0, 0, 1, 0, 1, 0, 1, 1, 1, 1, 0, 1, 0, 0, 1, 0, 1, 1, 1, 0, 0, 0, 1, 1, 0, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 0, 0, 0, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 0, 0, 0, 0, 1, 0, 0, 0, 1, 0, 1, 1, 1, 0, 1, 1, 1, 1, 0, 0, 0, 0, 0, 1, 0, 1, 0, 1, 1, 1, 1, 0, 0, 1, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 0, 0, 1, 0, 0, 1, 0, 0, 0, 0, 0, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 0, 1, 1, 1, 1, 0, 1, 0, 0, 1, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 1, 0, 1, 0, 0, 1, 0, 1, 1, 1, 0, 0, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 1, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 0, 0, 1, 0, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 1, 0, 0, 0, 0, 1, 1, 1, 1, 1, 0, 1, 1, 0, 1, 0, 1, 1, 1, 0, 1, 1, 1, 0, 1, 0, 1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 0, 1, 1, 1, 0, 1, 1, 0, 0, 1, 1, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 0, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 0, 0, 1, 1, 1, 0, 0, 0, 0, 0, 1, 1, 1, 0, 1, 1, 0, 1, 0, 1, 0, 0, 1, 1, 1, 1, 1, 1, 0, 0, 0, 1, 1, 0, 0, 1, 0, 1, 1, 0, 0, 0, 1, 0, 0, 0, 0, 1, 1, 0, 1, 0, 1, 0, 1, 0, 0, 1, 0, 1, 1, 1, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 0, 1, 0, 0, 1, 0, 1, 0, 1, 0, 1, 0, 0, 0, 1, 0, 0, 1, 0, 0, 1, 0, 1, 0, 0, 0, 0, 1, 1, 0, 1, 0, 1, 0, 0, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 0, 1, 0, 0, 1, 0, 0, 1, 0, 1, 1, 0, 0, 1, 0, 1, 0, 1, 0, 1, 1, 1, 0, 1, 0, 0, 1, 0, 0, 0, 0, 0, 1, 1, 1, 0, 1, 1, 0, 1, 0, 1, 0, 1, 1, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 0, 1, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 1, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 0, 0, 1, 0, 1, 0, 0, 1, 1, 1, 1, 0, 0, 1, 0, 0, 0, 1, 0, 0, 1, 0, 0, 0, 1, 1, 0, 1, 1, 0, 0, 0, 1, 0, 0, 0, 0, 0, 1, 0, 1, 0, 1, 0, 0, 1, 0, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 1, 0, 1, 0, 0, 0, 0, 1, 0, 0, 0, 1, 0, 1, 0, 1, 0, 0, 0, 0, 0, 0, 0, 1, 0, 0, 1, 1, 0, 1, 1, 1, 0, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 0, 0, 1, 0, 1, 0, 1, 0, 1, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 1, 0, 1, 0, 0, 1, 1, 1, 1, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 0, 0, 1, 0, 0, 0, 1, 0, 1, 0, 0, 0, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0, 1, 0, 0, 0, 0, 1, 0, 0, 0, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 0, 0, 0, 1, 1, 1, 0, 0, 1, 1, 1, 0, 1, 1, 1, 0, 1, 1, 1, 1, 0, 0, 0, 1, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 1, 0, 0, 0, 1, 1, 1, 1, 0, 0, 0, 1, 0, 0, 0, 0, 0, 1, 0, 1, 0, 1, 1, 1, 0, 0, 1, 0, 1, 1, 1, 0, 0, 1, 0, 0, 0, 0, 1, 0, 1, 1, 0, 0, 1, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 1, 0, 0, 1, 0, 0, 0, 0, 0, 0, 1, 0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 0, 1, 1, 0, 1, 0, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 1, 1, 0, 1, 0, 1, 1, 0, 1, 0, 1, 1, 1, 1, 0, 1, 1, 0, 0, 0, 0, 1, 0, 1, 0, 0, 0, 0, 0, 1, 1, 0, 1, 0, 0, 1, 1, 1, 0, 0, 1, 0, 1, 0, 1, 1, 0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 1, 0, 1, 1, 1, 1, 1]
Next steps
If you found this work interesting, you might be interested in the following material:
References
[1] Sciorilli, M., Borges, L., Patti, T. L., García-Martín, D., Camilo, G., Anandkumar, A., & Aolita, L. (2024). Towards large-scale quantum optimization solvers with few qubits. arXiv preprint arXiv:2401.09421.
Tutorial survey
Please take this short survey to provide feedback on this tutorial. Your insights will help us improve our content offerings and user experience.
© IBM Corp. 2024-2026